The Edge-Native Inference Gateway: Turning Unpredictable AI Opex into Fixed, Predictable Cost
For infrastructure leaders at industrial sites. How running AI models on your own hardware, behind one gateway, turns a cloud bill you cannot forecast into a fixed cost you can plan. You keep your data on site and still reach a large model when a task needs one.
Abstract
Pay-per-token cloud AI is one of the hardest costs to forecast. Every token, retry and agent loop adds to the bill, and the bill arrives after the money is spent. For factories, depots, substations and other regulated sites there is a better option. Run the models on hardware at the site and put one gateway in front of them. The gateway picks the right model for each request, reuses work it has already done, and checks safety and policy on every call. The result is a fixed cost for capacity, plus little more than the power bill for each extra request. Data stays on site and there is no cloud round-trip. This paper covers the architecture for the CTO, the cost model for the infrastructure VP, the main ways to cut token use, a three-year cost comparison and a deployment plan.
1The unpredictable-opex problem
AI moved from a pilot line item to a production dependency, and the bill followed. The trouble is not only that it is large — it is that it is unbounded and arrives in arrears.
Metered inference prices the wrong thing for an operator. You are billed per token, so cost scales with prompt length, retries, multi-turn agent loops, tool output pasted back into context, and traffic you do not control. A single agent that "thinks harder" or re-reads a large document can multiply the cost of an outcome by 10× with no change in business value. Budgets are set annually; token spend compounds daily. The result is a line item that finance cannot forecast and infrastructure cannot cap.
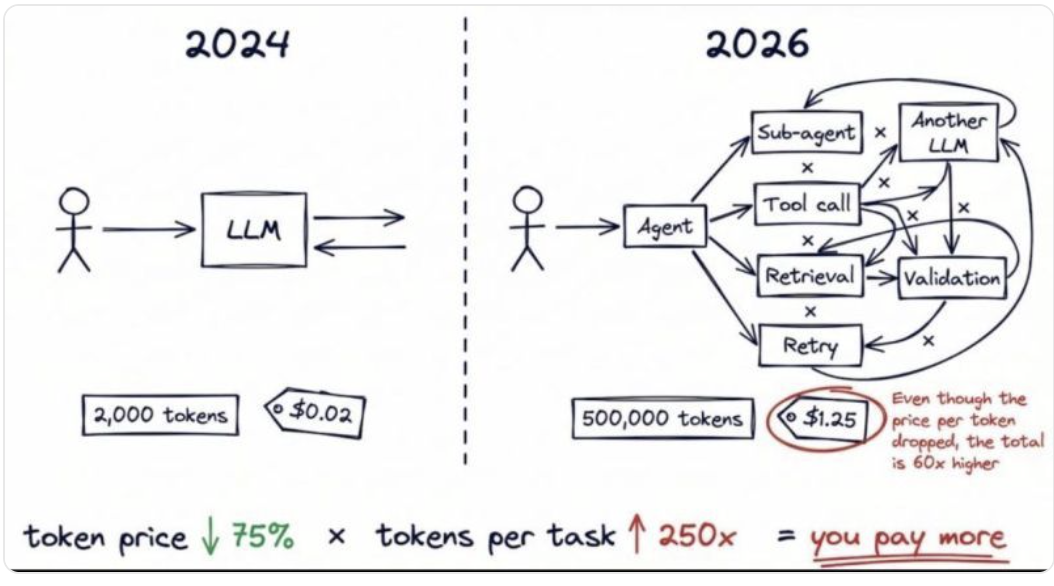
For the industrial edge three more constraints stack on top of cost:
- Data gravity and sovereignty. Telemetry, video, control logs and process data are large, sensitive, and often regulated. Shipping them to a cloud model is a governance liability and an egress bill.
- Latency and availability. A line, a vehicle or a substation cannot wait on a round-trip to a region, and cannot stop when the link does.
- Determinism. Operations need the same answer, at the same latency, at the same cost — not a number that drifts with a vendor's pricing or capacity.
Stop renting inference by the token for steady-state industrial workloads. Put custom-built capacity where the data is, and govern every request through one gateway — so cost becomes a fixed price you plan, not opex you discover.
2Architecture: the edge-native inference gateway
The gateway is not a proxy bolted in front of a model. It is the control point where workload, routing, serving, caching and policy meet — designed from the inference engine out, not around it.
Every request goes through the gateway, which chooses the model that should handle it. That might be a small local model, a large on-site model or, only when it really pays, an external model. The same gateway reuses work it has already done, sends only the context a request needs, and checks safety and policy on every call.
3Why edge-native — the CTO view
Edge-native is an architectural choice before it is a cost choice. It changes where data lives, where decisions happen, and what you can guarantee.
| Property | Cloud-metered inference | Edge-native gateway on on-site hardware |
|---|---|---|
| Data path | Sensitive data egresses to a third party | Data stays on-prem; nothing leaves the boundary |
| Latency | Region round-trip + queue, variable | Local, deterministic, sub-network |
| Availability | Depends on the link and the vendor | Runs through link and provider outages |
| Sovereignty | Subject to external jurisdiction & retention | Wholly within your governance domain |
| Reversibility | Vendor sets pricing, models, deprecations | You version, shadow-test and revert policy |
| Cost shape | Variable opex, billed in arrears | Fixed price for capacity + near-electricity marginal cost |
The gateway is what makes "edge-native" operationally real rather than a pile of GPUs. It gives one place to set
policy, one place to meter spend, one industry-standard API ingress so applications do not change, and one
lifecycle (shadow → activate → revert) so routing never drifts silently. Capability is not
sacrificed: hard requests still reach a large on-prem model, and the rare request that truly needs a frontier model
can still take that path — by exception, under policy, with the cost attributed.
4Four token-economics levers
Fixed, on-site capacity caps the denominator (you stop paying per token). The gateway shrinks the numerator — the work each outcome actually costs — with four compounding levers.
| Lever | Mechanism | Effect on cost-per-outcome |
|---|---|---|
| Signal-driven routing | Each request is classified by intent, complexity, risk and modality; mechanical and easy turns go to small local models, and reasoning is invoked only when it pays. | Routed paths run at a small fraction of an always-large path |
| Prefix-cache discipline | Stable prompt prefixes, deterministic tool schemas and bounded, append-only context keep reusable prefixes intact across a long session. | Cached tokens are reused at a steep discount instead of recomputed every turn |
| Context selection | The gateway sends the evidence a turn needs — selected, bounded and compressed — rather than pasting whole documents and tool dumps. | Large reductions in prompt and tool-output tokens, with continuity preserved |
| Semantic caching | Semantically-equivalent requests reuse a prior answer instead of triggering fresh inference. | Repeat and near-repeat traffic costs nothing to serve |
5The economics — the Infra-VP view
The job is not to minimize this month's invoice; it is to make next year's number knowable. Edge-native does that by changing the shape of the cost curve.
Metered inference is a line that rises with usage and never flattens; every new agent, every longer prompt, every retry adds to it forever. Fixed capacity is a step (the hardware) followed by a nearly flat line (power, space, support); taken as a service, it is a flat fee from the start. Past a modest, steady utilization the two curves cross — and beyond the crossover, every additional unit of work on that capacity is effectively free relative to the meter.
6Custom-built hardware accelerators
Predictable economics need predictable units. Unovie custom-builds the hardware accelerators to meet agentic performance, low-latency and high-availability requirements, configured, tested and supported with the platform, on two complementary platforms that cover the develop-and-serve lifecycle on your site.
NVIDIA DGX Spark — the on-prem development & large-model node
A GB10 Grace Blackwell desktop supercomputer with 128 GB of coherent unified memory and roughly 1,000 TFLOPS (FP4) of AI compute — enough to prototype, fine-tune and serve models up to ~200B parameters locally, or ~405B across a linked pair over its built-in high-speed fabric. It runs the same container stack as the datacenter, so what you build here promotes to the edge unchanged.
AMD Ryzen AI Max+ 395 — the private inference node
A small, all-metal node fusing 16 Zen 5 cores, a Radeon 8060S iGPU and an XDNA 2 NPU for ~126 TFLOPS of platform AI, with 128 GB of LPDDR5X-8000 — enough to keep 70B-class models resident and private. Capacity grows by adding fixed-price units, so cost goes up in known steps.
7A three-year TCO comparison
An illustrative model for a single industrial site running a steady mix of copilots, vision triage and maintenance queries. Figures are directional — the point is the shape, not a quote.
| Dimension | Metered cloud inference | Edge-native gateway (Unovie hardware) |
|---|---|---|
| Upfront cost | ~$0 | Custom-built node fleet and setup from Unovie: bought outright, or as a service with no upfront cost |
| Recurring cost | Per-token bill that grows with usage, retries and context | Power, space and Unovie support (or the service fee) — roughly flat |
| Marginal cost of +1 request | Full token price, every time | Approaches electricity once capacity exists |
| Data egress | Per-GB transfer for telemetry, video, documents | None — data never leaves the site |
| Budget predictability | Forecast error grows with adoption | Known within power and capacity envelopes |
| 3-year trajectory | Rises every quarter; no natural ceiling | Step at year 0, near-flat thereafter |
| Exit / change cost | Re-platform on vendor pricing & deprecations | Models, playbooks and evidence stay yours; policy versioned and reversible |
For steady-state industrial workloads, edge-native turns "how much will AI cost next year?" from a forecast into a capacity-planning question — the same discipline you already apply to compute, storage and network.
8Industrial edge use cases
| Use case | Why edge-native | Primary saving |
|---|---|---|
| Vision QC on the line | High-rate video can't egress; needs sub-second local decisions | No egress; small-model routing on repetitive frames |
| Predictive maintenance | Continuous sensor streams, mostly normal; rare anomalies | Cache + cheap path for normal; reserve large model for anomalies |
| OT / IT security | Detection must run in the data path, on-prem, always-on | Local inference; no telemetry leaves the boundary |
| Field & control-room copilots | Repetitive shift queries; must work offline and fast | High cache & small-model hit rates; predictable cost |
| Regulated document & agent automation | Sensitive records can't be sent to third-party models | Sovereignty; context selection trims long-document tokens |
9Deployment blueprint
- Develop on the large node. Prototype, fine-tune and evaluate on the on-prem development supercomputer; keep models and data inside the boundary.
- Promote unchanged. Ship the same containers to a fleet of small edge inference nodes — one pipeline, one artifact, one cost basis.
- Front everything with the gateway. All traffic flows through one industry-standard API ingress that routes by signal, reuses prefixes, selects context, and enforces safety.
- Meter and attribute. Every route is logged with latency, tokens and cost, so spend is accountable per team and per workload — while the task runs, not after.
- Shadow, activate, revert. Test every routing or policy change on replayed traffic before activation, with one-click rollback.
- Scale by units, not by meter. Add fixed-price nodes to the cluster as demand grows; the cost curve stays a series of known steps.
10Governance, safety & reversibility
Keeping the inference path on site is also the strongest governance posture available. Sensitive context never leaves the site, so leaked vectors and prompts handed to models you do not control — a business liability and a governance violation — simply cannot happen. Safety classifiers for sensitive-data leakage, prompt injection and unsafe output run inline on every turn, not as an afterthought. Tools and code execute in policy-governed sandboxes. And because the whole control plane is versioned, every change is shadow-tested and reversible — the opposite of a vendor deprecating a model under you.
11Recommendations & checklist
- Inventory steady-state workloads. Repetitive, high-volume, latency- or sovereignty-sensitive traffic is the first to move edge-native.
- Plan capacity, not tokens, for that traffic. Size the Unovie node fleet to steady demand; keep a frontier path for the long tail.
- Make the gateway the single ingress. One entry point, one policy plane, one meter, compatible APIs so apps don't change.
- Turn on all four levers. Routing, prefix-cache discipline, context selection and semantic caching compound.
- Keep data on-prem by default. Treat egress as an exception that needs justification.
- Version and shadow-test policy. Never let routing drift silently; always be able to revert.
- Attribute cost continuously. Per-route metering turns AI spend into a capacity-planning input.
- Plan the two-tier fleet. Develop on the large node; serve on small nodes; promote artifacts unchanged.
12References
- NVIDIA (2026). DGX Spark — Personal AI Supercomputer (GB10 Grace Blackwell). 128 GB LPDDR5X coherent unified memory; ~1,000 TFLOPS FP4; high-speed fabric for linked-pair scaling.
- AMD (2026). Ryzen AI Max+ 395 (Strix Halo). 16 Zen 5 cores, Radeon 8060S iGPU, XDNA 2 NPU; ~126 platform AI TFLOPS; 128 GB LPDDR5X-8000.
- Workload–router–pool architecture for inference optimization (2026). Signal-driven routing across a mixture of models by cost, capability, privacy and risk.
- When-to-reason routing (2025). Invoking expensive reasoning paths only when expected value justifies the cost.
- Category-aware semantic caching for heterogeneous workloads (2025). Reusing answers for semantically-equivalent requests.
- Prefix / KV-cache reuse in high-throughput serving. Cached prompt prefixes billed at a steep discount versus recomputation.
- Inference-native agent harness practice (2026). Prefix-cache discipline, context selection and bounded tool output for long-horizon work.
- Unovie.AI. Device Platform. unovie.ai/device-platform